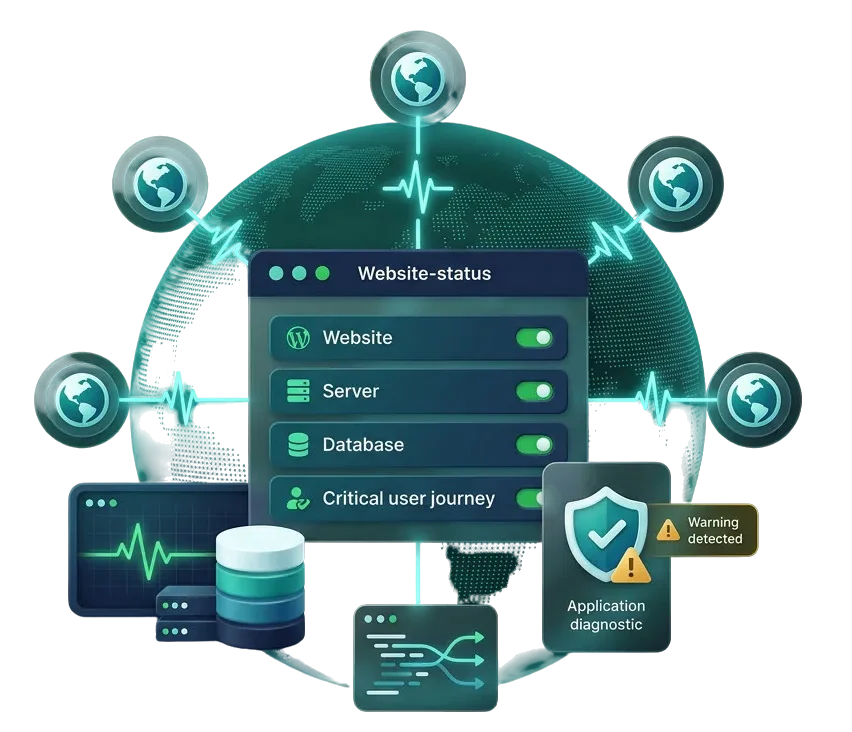
Silent downtime, failed background cron tasks, broken checkout funnels, and unhandled server memory spikes can drain revenue for hours before anyone notices. Relying on basic ping checks fails to detect partial outages, frozen databases, or unresponsive third-party APIs. We deliver full-stack application monitoring, automated health probes, database performance tracking, and rapid developer response so your WordPress business remains fast, stable, and completely dependable.
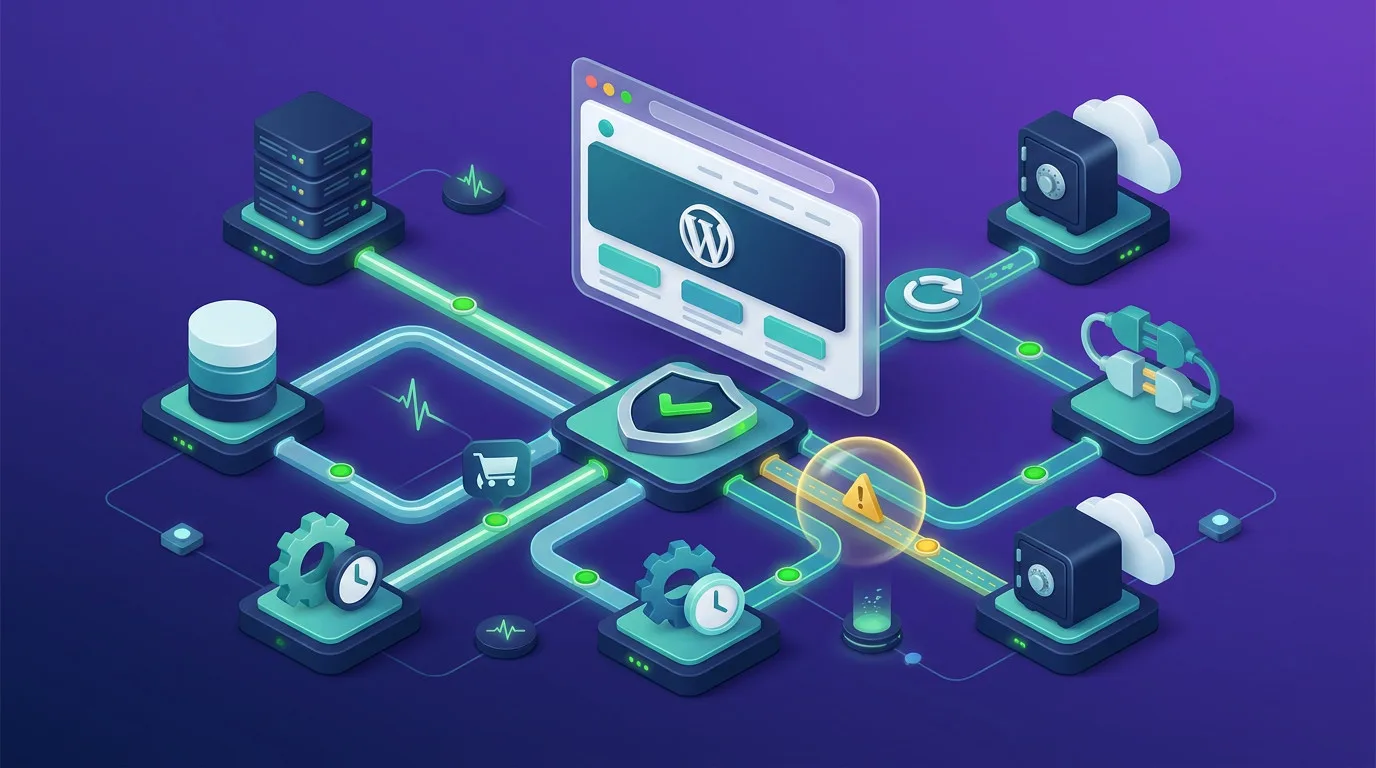
We monitor your website from multiple global nodes every 60 seconds to catch and resolve outages instantly.
We monitor PHP fatal errors, database connection drops, and memory exhaustion warnings directly from server logs.
We run headless simulated checkouts and form submissions to verify mission-critical funnels never fail silently.
We track CPU load, RAM utilization, MySQL query bottlenecks, and disk capacity before server crashes occur.
A simple HTTP 200 ping check from a standard uptime tool can return “healthy” even when your database is locked, your payment gateway is failing, or your cart screen displays a white screen. Real site reliability requires deep application-level telemetry. We track real-time server health, script execution thresholds, cron queues, and interactive user flows. The moment an error threshold is breached, our engineers step in to isolate the conflict and restore service before your business suffers revenue loss.
Do not guess how your website handles unexpected traffic spikes or automated background jobs. We configure clear status dashboards and telemetry feeds right inside your client portal. You get real-time visibility into global response times, error rates, server resources, and resolution logs, giving your leadership team complete confidence in your online infrastructure.
Protect flash sales and holiday shopping periods from sudden crashes. We monitor payment webhook responsiveness, cart operations, and database concurrency so checkout never freezes under load.
Provide agency clients with enterprise-grade uptime monitoring and technical peace of mind. We act as your behind-the-scenes incident response team, fixing crashes before clients even notice.
Scale your user base without server meltdowns. We profile server resource consumption, identify slow queries, and ensure background tasks scale smoothly alongside your growing traffic.
Ensure high-spend advertising traffic always lands on a fast, responsive page. We alert and resolve server throttling, CDN hiccups, and broken form scripts so ad budgets generate returns.
$ 49.00
$ 99.00
$ 199.00
$ 490.00
$ 990.00
$ 1990.00
Project Step 1
“We inspect your server stack, host architecture, third-party API dependencies, database configuration, and critical user funnels to identify potential single points of failure.”
Project Step 2
“We design custom monitoring rules defining response latency limits, memory usage ceilings, error code alerts, and escalation pathways. You receive a clear reliability runbook before deployment.”
Project Step 3
“We configure client status dashboards and notification channels (Slack, SMS, email) so your stakeholders receive clear, transparent operational health updates whenever required.”
Project Step 4
“We provision multi-region ping monitors, configure headless synthetic transaction tests for forms and checkout, and connect server daemon listeners to stream error logs.”
Project Step 5
“We simulate database drops, 500 error triggers, and slow response states on a staging environment to confirm alert routing fires within seconds and engineering runbooks trigger properly.”
Project Step 6
“We launch 24/7 active monitoring across your live website, confirm telemetry data feeds, and provide full documentation detailing your site’s ongoing reliability protocols.”
Share your website URL and hosting details with us to get a complete infrastructure audit, monitoring plan, and clear quote.